Website Thumbnail Generation: Capture, Resize, Store and Refresh
Build a website thumbnail pipeline: capture once at 1280×800, resize with sharp for each display size, store by hash, queue with async jobs and refresh.
A thumbnail is a small picture of a web page that sits next to a link: a card in a startup directory, a row in a bookmarking app, a tile in a portfolio. This guide covers building the pipeline that produces those images and keeps them current. It is written for developers who own the storage and the display.
If you want the product overview, see the website thumbnails use case. This article covers implementation: which size to capture, how to resize, where to store, how to queue and refresh, and what to do when a capture fails.
Thumbnails are a different job from two related ones:
- Open Graph images for your own pages. You design a card and publish it in
og:image. See dynamic OG image generation. - Link previews for URLs your users paste. Here the page's own metadata comes first and a screenshot is the fallback. See building a link preview service.
Capture size vs. display size
The most common mistake is to capture at the size you display. A 320-pixel-wide viewport renders the site's mobile layout, which rarely looks like the site people know. Capture at a desktop width, then scale down.
A practical setup is a single 1280×800 capture (16:10). Every display size below is derived from it:
| Where the thumbnail appears | Display box (CSS px) | Files to generate | Why |
|---|---|---|---|
| Compact list or bookmark row | 160 × 100 | 160w, 320w | The 320w file covers 2× screens |
| Directory grid card | 320 × 200 | 320w, 640w | Most common card size; 640w for 2× |
| Portfolio or featured tile | 480 × 300 | 480w, 960w | The 960w file is still a downscale from 1280 |
These numbers are examples, not a standard. Use your own layout's box sizes. Keep two rules:
- Match the aspect ratio of the capture to the slot, or decide deliberately where the crop happens. For a 4:3 slot, crop from the top (
position: 'top') so the header and hero stay in frame. - Never upscale. If the largest file must be wider than 1280 pixels, request
deviceScaleFactor: 2. That keeps the 1280×800 CSS layout but returns a 2560×1600 image. Expect larger files and longer processing.
For choosing a viewport by task more generally, see how to choose a screenshot viewport.
The capture request
Width and height are top-level fields. You need to send both: a custom size is used only when width and height are both present. Don't send device with them, because a device preset overrides custom dimensions.
{
  "url": "https://example.com",
  "width": 1280,
  "height": 800,
  "format": "png",
  "blockAds": true
}
format: "png"gives a lossless source for resizing. You'll encode to WebP afterwards, so the source format only affects transfer size.blockAdshides common ad and consent containers. It's available on every plan.- Growth plans can add
aiRemoval(typescookie-banner,newsletter,chat-widget,social-overlay,ad) for overlays thatblockAdsmisses. - For pages that render content late, add
waitForNetworkIdle: trueor a shortdelay(up to 10,000 ms). See capturing dynamic content.
Capture once, resize locally
The module below captures one source image and renders every size with sharp. It needs Node.js 18 or later (for global fetch) and npm install sharp.
// thumbnails.mjs
import crypto from 'node:crypto';
import sharp from 'sharp';

const API_URL = 'https://screenshotly.app/api/screenshot';

export const CAPTURE = { width: 1280, height: 800, format: 'png' };

export const SIZES = [
  { width: 160, height: 100 },
  { width: 320, height: 200 },
  { width: 480, height: 300 },
  { width: 640, height: 400 },
  { width: 960, height: 600 },
];

export async function captureSource(url, extra = {}) {
  const res = await fetch(API_URL, {
    method: 'POST',
    headers: {
      'x-api-key': process.env.SCREENSHOTLY_API_KEY,
      'content-type': 'application/json',
    },
    body: JSON.stringify({ url, ...CAPTURE, blockAds: true, ...extra }),
  });
  if (!res.ok) {
    const error = new Error(`Capture failed (${res.status}): ${await res.text()}`);
    error.status = res.status;
    error.retryAfter = Number(res.headers.get('retry-after')) || undefined;
    throw error;
  }
  return Buffer.from(await res.arrayBuffer());
}

export async function renderSizes(source) {
  const files = {};
  for (const size of SIZES) {
    files[size.width] = await sharp(source)
      .resize(size.width, size.height, { fit: 'cover', position: 'top' })
      .webp({ quality: 80 })
      .toBuffer();
  }
  return files;
}

export function thumbnailKey(url, extra = {}) {
  const normalized = new URL(url);
  normalized.hash = '';
  const input = JSON.stringify({ url: normalized.href, ...CAPTURE, ...extra });
  return crypto.createHash('sha256').update(input).digest('hex').slice(0, 32);
}
A few details matter here:
- The key includes the capture options. If you change the viewport or add
aiRemoval, you get new keys and old files don't get mixed in. - The fragment is dropped, because
#sectiondoesn't change what the server returns. Don't strip query strings: on many sites they select different content. - The API key stays on the server. The capture endpoint requires your key, so browsers should never call it directly. They load your stored files.
What the pipeline produces
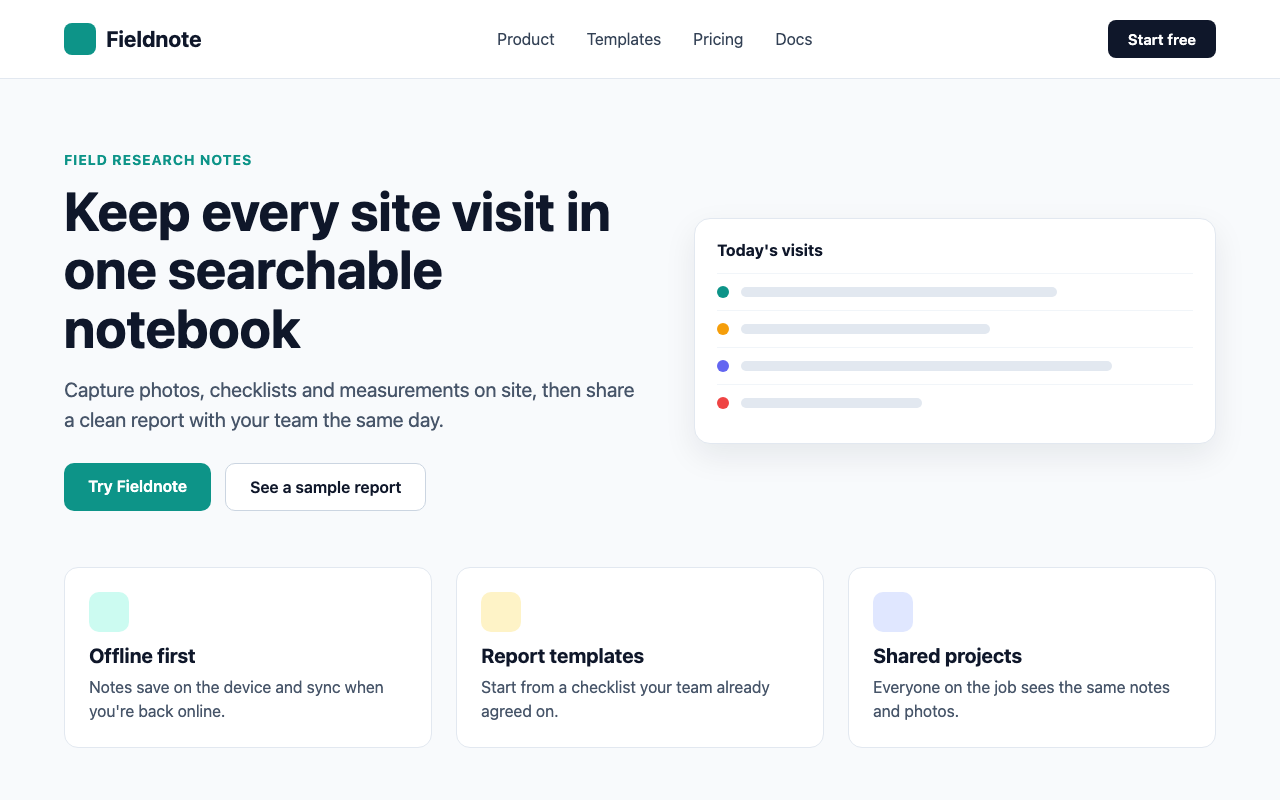
Here is the pipeline's output for a test page. The source capture is 1280×800:
The same capture after renderSizes(), shown as the 320×200 card file (the 640×400 file is served to high-density screens through srcset):
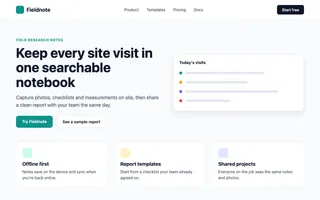
At 320 pixels wide the body copy isn't legible, and it doesn't need to be. The thumbnail is recognizable because it keeps the desktop layout. A capture with a 320-pixel viewport would have shown this page's single-column mobile layout instead.
Source: Fieldnote is a fictional, self-contained fixture page (no external fonts, images or scripts) served from a local server. It was captured with Screenshotly's own capture code running locally in headless Google Chrome 157 on macOS, using the request body from the capture request above, then resized with the renderSizes() function in the module above. The only change for the local run was to the URL-safety check, which normally rejects local addresses and was set to allow only the fixture server. These images were not captured through the hosted API, and font rendering on the hosted service may differ slightly. The thumbnails are the WebP files as generated; the capture is the PNG source.
Store files under the hash
Write each size to your own bucket or CDN origin and save the keys in your database. This example uses the AWS SDK v3 S3 client. Any object store works the same way.
// store.mjs
import { S3Client, PutObjectCommand } from '@aws-sdk/client-s3';
import { captureSource, renderSizes, thumbnailKey } from './thumbnails.mjs';

const s3 = new S3Client({});
const BUCKET = process.env.THUMBNAIL_BUCKET;

export async function generateAndStore(url) {
  const key = thumbnailKey(url);
  const files = await renderSizes(await captureSource(url));

  for (const [width, body] of Object.entries(files)) {
    await s3.send(new PutObjectCommand({
      Bucket: BUCKET,
      Key: `thumbs/${key}-${width}.webp`,
      Body: body,
      ContentType: 'image/webp',
      CacheControl: 'public, max-age=31536000, immutable',
    }));
  }

  return { key, capturedAt: new Date().toISOString() };
}
Because the object key changes whenever the capture options change, you can serve the files with long-lived immutable caching. A refresh writes to the same key, so either purge your CDN for those paths or add a version segment (for example, capturedAt as a timestamp) to the path.
Screenshotly also has a storage: { "enabled": true } option (Basic and up). It returns JSON with a signed url instead of the image bytes. That link expires after 24 hours, so it suits handing a result to another worker, not embedding in your pages. For thumbnails, copy the bytes into storage you control.
Serve the sizes with srcset so browsers pick the right file:
<img
  src="/thumbs/3f9c1e2a-320.webp"
  srcset="/thumbs/3f9c1e2a-320.webp 320w, /thumbs/3f9c1e2a-640.webp 640w"
  sizes="320px"
  width="320"
  height="200"
  alt="Homepage of example.com"
  loading="lazy"
>
Setting width and height reserves the space, so the grid doesn't shift while images load.
Queue large backfills with async jobs
A synchronous request holds a connection open while the browser renders. That's fine for one URL. For a directory backfill of thousands of sites, use durable jobs (Basic plan or higher). POST /api/jobs takes the same body as the synchronous endpoint, commits the job, and returns 202 with an ID and a status URL. The worker makes up to three attempts per capture, with backoff between them.
// jobs.mjs
const BASE = 'https://screenshotly.app';
const headers = {
  'x-api-key': process.env.SCREENSHOTLY_API_KEY,
  'content-type': 'application/json',
};

export async function enqueueThumbnail(url, idempotencyKey) {
  const res = await fetch(`${BASE}/api/jobs`, {
    method: 'POST',
    headers: { ...headers, 'Idempotency-Key': idempotencyKey },
    body: JSON.stringify({ url, width: 1280, height: 800, format: 'png', blockAds: true }),
  });
  if (!res.ok) throw new Error(`Enqueue failed (${res.status}): ${await res.text()}`);
  return res.json(); // { id, status, replayed, statusUrl }
}

export async function waitForJob(statusUrl, { intervalMs = 3000, timeoutMs = 180000 } = {}) {
  const deadline = Date.now() + timeoutMs;
  while (Date.now() < deadline) {
    const res = await fetch(`${BASE}${statusUrl}`, { headers });
    if (!res.ok) throw new Error(`Status check failed (${res.status})`);
    const job = await res.json();
    if (job.status === 'SUCCEEDED') return job;
    if (job.status === 'FAILED' || job.status === 'CANCELED') {
      throw new Error(`Job ${job.id} ${job.status}: ${job.errorMessage ?? job.errorCode ?? 'no detail'}`);
    }
    await new Promise((resolve) => setTimeout(resolve, intervalMs));
  }
  throw new Error('Timed out waiting for capture job');
}

export async function downloadResult(job) {
  const res = await fetch(job.resultUrl);
  if (!res.ok) throw new Error(`Download failed (${res.status})`);
  return Buffer.from(await res.arrayBuffer());
}
Notes on the job API:
statusUrlis a relative path (/api/jobs/{id}), so prefix it with the API origin.resultUrlis short-lived. It's a signed link that is valid for about 15 minutes. Download it right away and pass the bytes torenderSizes. If it expires, read the job again to get a fresh link. The stored result itself is kept according to your account's retention setting (1 to 30 days).- Idempotency keys make retries safe. Repeating a request with the same
Idempotency-Keyreturns the original job instead of creating a second one. Keys can be up to 200 printable ASCII characters. For a refresh you want a new job, so put the refresh date in the key, for examplethumb-${thumbnailKey(url)}-2026-11-13. - Webhooks replace polling. Set
webhook.urlon the job, and Screenshotly calls your endpoint when the job finishes. See the webhooks guide.
On Growth and Scale, POST /api/jobs/batch takes up to 20 captures per request and returns one job per item:
{
  "captures": [
    { "url": "https://example.com", "width": 1280, "height": 800, "format": "png", "blockAds": true },
    { "url": "https://example.org", "width": 1280, "height": 800, "format": "png", "blockAds": true }
  ]
}
// batch.mjs
const BASE = 'https://screenshotly.app';

export async function enqueueBatch(urls, batchKey) {
  const jobs = [];
  for (let i = 0; i < urls.length; i += 20) {
    const chunk = urls.slice(i, i + 20);
    const res = await fetch(`${BASE}/api/jobs/batch`, {
      method: 'POST',
      headers: {
        'x-api-key': process.env.SCREENSHOTLY_API_KEY,
        'content-type': 'application/json',
        'Idempotency-Key': `${batchKey}-${i / 20}`,
      },
      body: JSON.stringify({
        captures: chunk.map((url) => ({ url, width: 1280, height: 800, format: 'png', blockAds: true })),
      }),
    });
    if (!res.ok) throw new Error(`Batch failed (${res.status}): ${await res.text()}`);
    const body = await res.json();
    jobs.push(...body.jobs);
  }
  return jobs; // [{ id, status, replayed, statusUrl }, ...]
}
The batch endpoint checks your remaining monthly allowance first. It returns 429 if the batch is bigger than what you have left, so size your chunks to your plan. Full details are in the async jobs reference. For concurrency patterns outside the job API, see batch screenshot processing.
Refresh policy
Thumbnails go stale when sites redesign. A workable policy has two parts.
Age-based refresh. Store capturedAt for each URL. Run a daily task that queues anything older than your threshold. For example, use 7 days for featured listings and 30 days for everything else. Spread the work across the day so you stay inside your rate limit.
On-demand refresh. Give site owners or moderators a "refresh thumbnail" action that queues one job right away. This catches redesigns faster than any schedule.
Don't base refreshes on Last-Modified or ETag alone. Many HTML responses don't send them. Others change them on every deploy or request, so they tell you little about whether the page looks different.
Failures and fallbacks
Most errors fall into a few groups. Handle each one differently:
| Response | Meaning | What to do |
|---|---|---|
400 |
Invalid body, an unsafe URL (private or internal address), or a selector not found | Don't retry. Mark the listing and show a fallback. |
401 / 403 |
Bad key, or a feature needs a higher plan (minimumPlan in the body) |
Configuration problem. Alert, don't retry. |
429 |
Rate or quota limit | Wait for Retry-After, then resume. |
500 / 503 |
Capture failed, for example a navigation timeout (30 s) or the site refused the browser | Retry later with backoff. Fall back after a few attempts. |
Failed captures don't count against your monthly quota.
When a capture keeps failing, use this fallback order:
- The page's own
og:image. Fetch it through an SSRF-safe fetcher, check it's a real image, and copy it into your storage. Never hotlink it. The link preview guide has a fetcher you can reuse. - A placeholder with the site's domain or favicon.
- A retry later. Record the failure count and try again on the next refresh cycle.
Some sites block automated browsers. Screenshotly has a stealth option (Basic and up) that sends a desktop browser user agent and hides some automation signals, but it doesn't guarantee access. Respect a site's terms, and rely on the fallback rather than escalating.
For more on retry logic, see the error handling guide.
Plan requirements
| Capability | Minimum plan |
|---|---|
Synchronous PNG/JPEG/WebP capture, blockAds, deviceScaleFactor |
Free |
Async jobs (/api/jobs), cache, storage, webhook, stealth |
Basic |
Batch jobs (up to 20 per request), aiRemoval, hideSelectors |
Growth |
The Free plan includes 100 captures in total, which is enough to test the pipeline end to end. See pricing for monthly allowances.
Checklist
- Capture once per URL at a desktop viewport. Resize locally for every display size.
- Key files by a hash of the normalized URL plus capture options.
- Store in your own bucket and serve with
srcsetand explicit dimensions. - Use async jobs for backfills, with idempotency keys and dated refresh keys.
- Refresh by age and on demand. Don't trust
Last-Modifiedfor visual changes. - Fall back to
og:image, then a placeholder, and retry later.
You can try capture options in the playground before wiring up the queue, or create a free account to get an API key.
About the Author

Asad Ali
CTO at ZTABS and the developer behind Screenshotly. Writes about screenshot automation, API design, and building reliable SaaS backends with Next.js, Node.js, and TypeScript.
Credentials: CTO at ZTABS, full-stack developer, builder and maintainer of Screenshotly and its official JavaScript and Python clients
Frequently Asked Questions
Can the Screenshotly API return a resized thumbnail directly?
No. The API has no resize option. Request a capture with top-level width and height (for example 1280×800), then resize it yourself. In Node.js, sharp works well. One capture can produce every display size you need, so you pay for one capture per URL instead of one per size.
What capture size should I use for thumbnails?
Pick a viewport that shows the layout you want people to recognize, usually the desktop layout, with the same aspect ratio as your thumbnail slot. 1280×800 (16:10) is a reasonable starting point for card grids. If your largest rendered file must be wider than the capture, use deviceScaleFactor 2 rather than upscaling.
Which plan do I need for a thumbnail queue?
Synchronous captures in PNG, JPEG or WebP work on every plan, including Free. Durable async jobs (POST /api/jobs) need Basic or higher. Batch submission of up to 20 captures per request (POST /api/jobs/batch) needs Growth or higher.
How often should thumbnails be refreshed?
Use an age-based schedule that matches how often your listed sites change, plus an on-demand refresh button for owners or moderators. Don't depend on Last-Modified or ETag headers. Many HTML pages omit them or change them on every deploy, so they say little about whether the page looks different.
What should I show when a site can't be captured?
Fall back to the page's own og:image, fetched through an SSRF-safe fetcher and copied into your storage, then to a placeholder. Record the failure and retry later instead of retrying immediately. Some sites block automated browsers, and Screenshotly doesn't promise to get past that.
Ready to capture your first screenshot?
Get started with 100 free screenshots. No credit card required.